All projects
Understanding the Limits of Latent World Models
World models are widely proposed as core components for enabling agents to reason over long temporal and spatial horizons. Yet current evaluations often emphasize task performance while providing limited insight into whether learned world models acquire predictive latent dynamics that reflect the underlying structure of the environment. Here we introduce the concept of faithful latent world models as an equivariance condition between the environment’s transition map and the learned latent dynamics. We propose latent rollout consistency (LRC) as a metric to evaluate action-conditioned latent prediction. Strikingly, we find that across the studied state of the art latent world models, none solves the task by actually faithfully modeling the dynamics of the environment.
What does it take to model the world?
We call a latent world model faithful when its representation preserves the environment state and its latent dynamics evolve consistently with the true dynamics under the same actions.
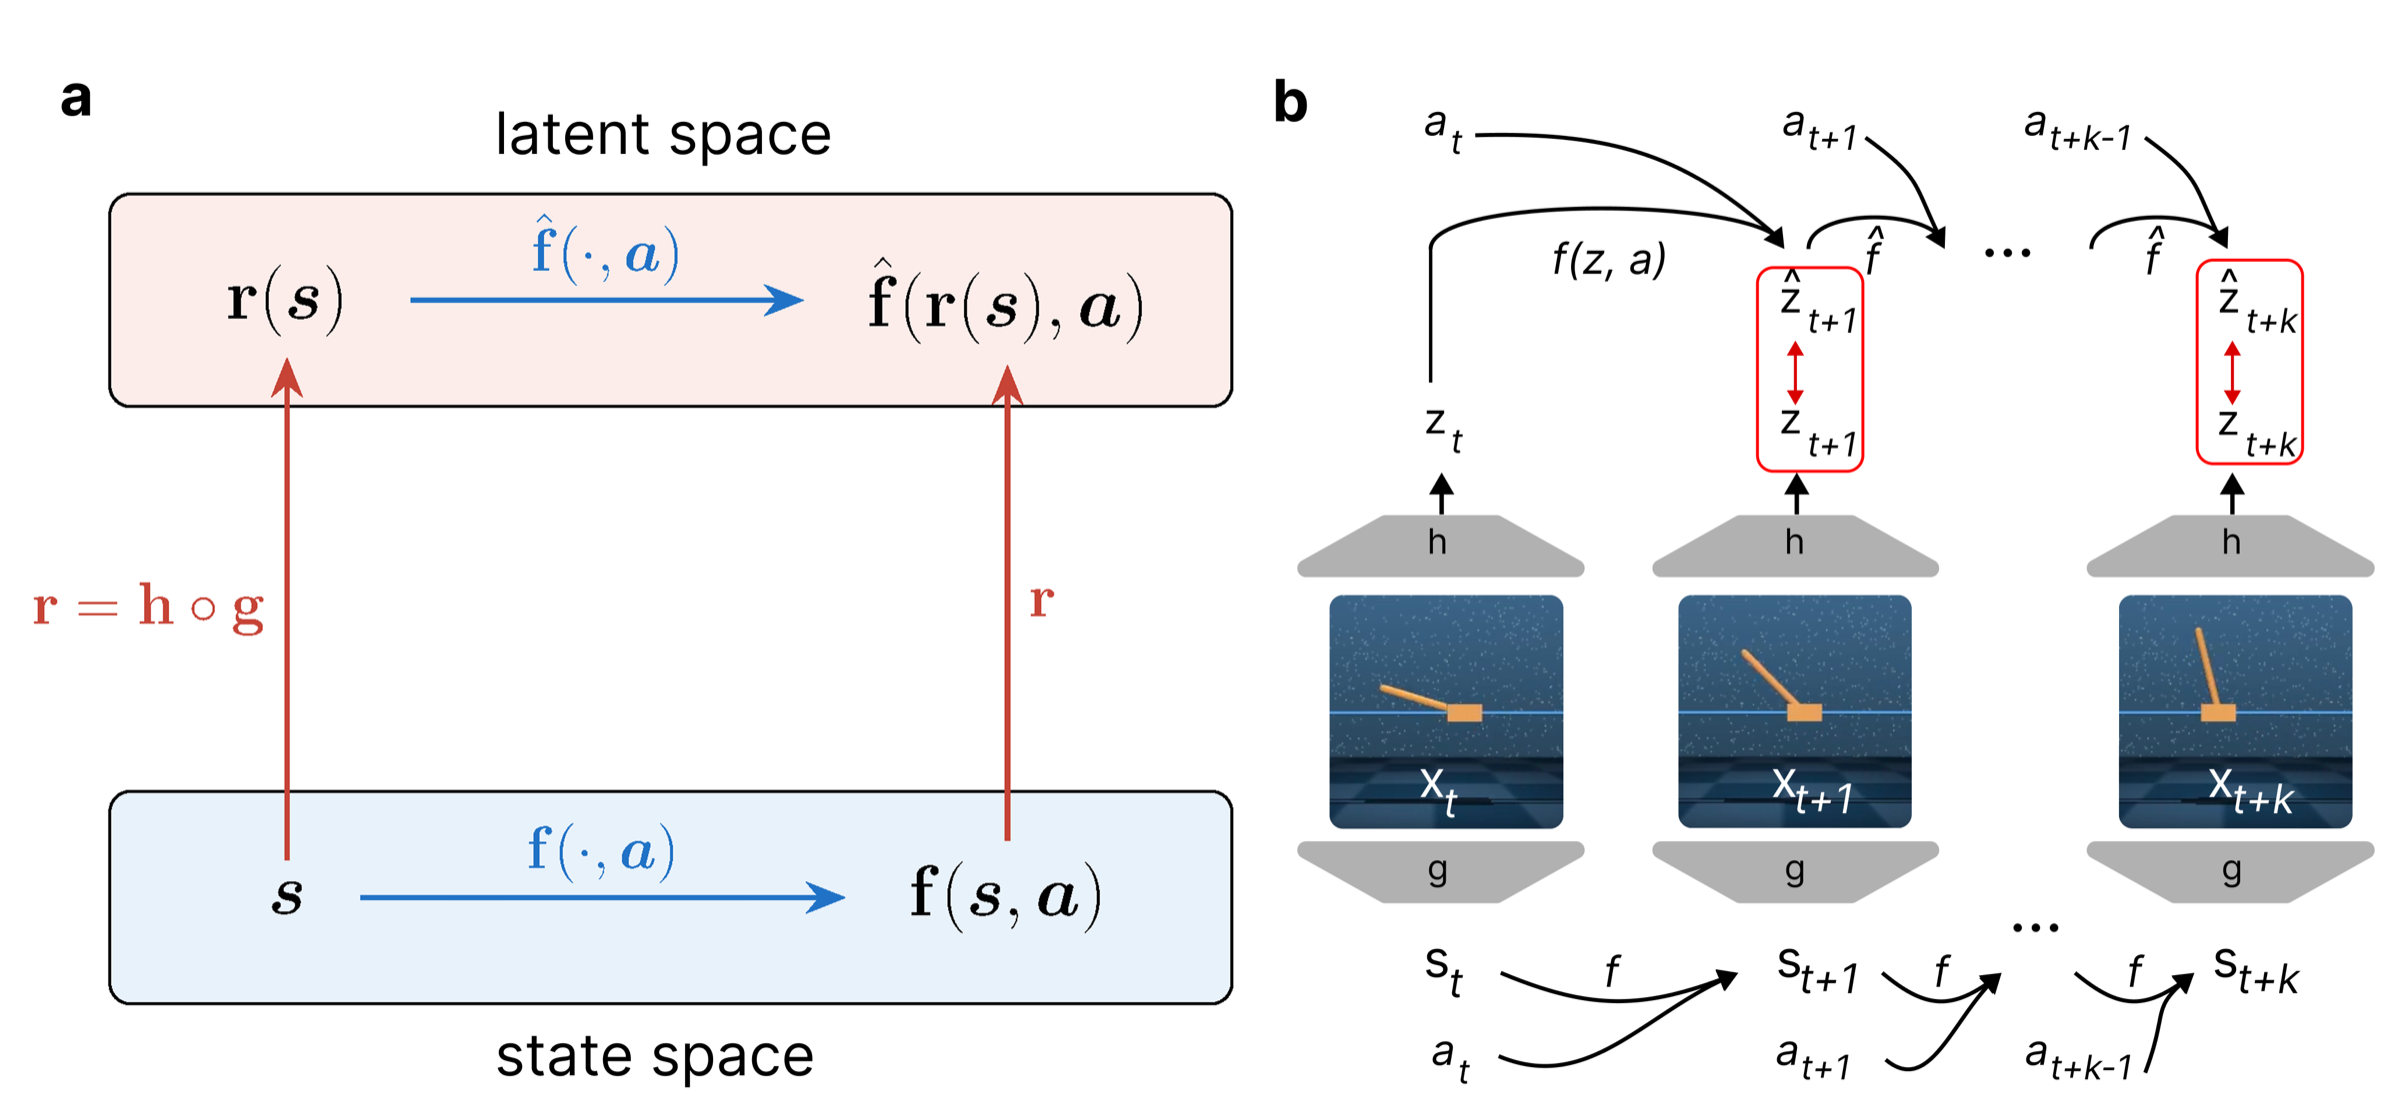
The environment evolves as and is observed as . A latent world model infers from observations and predicts . With the state-to-latent map , the model is faithful if it satisfies two conditions. The first, dynamics equivariance, requires for all states and actions : encoding after a true transition agrees with predicting in latent space. The second, state sufficiency, requires to be injective, so that the representation retains the full state.
We measure dynamics equivariance with latent rollout consistency (LRC), the between the latent predicted autoregressively over steps and the latent inferred from the realized trajectory:
A faithful model has an LRC of 100% at every horizon. High LRC alone is not sufficient, because a collapsed representation can be easy to predict. Post-hoc state decoders therefore test how much of the state the representation retains.
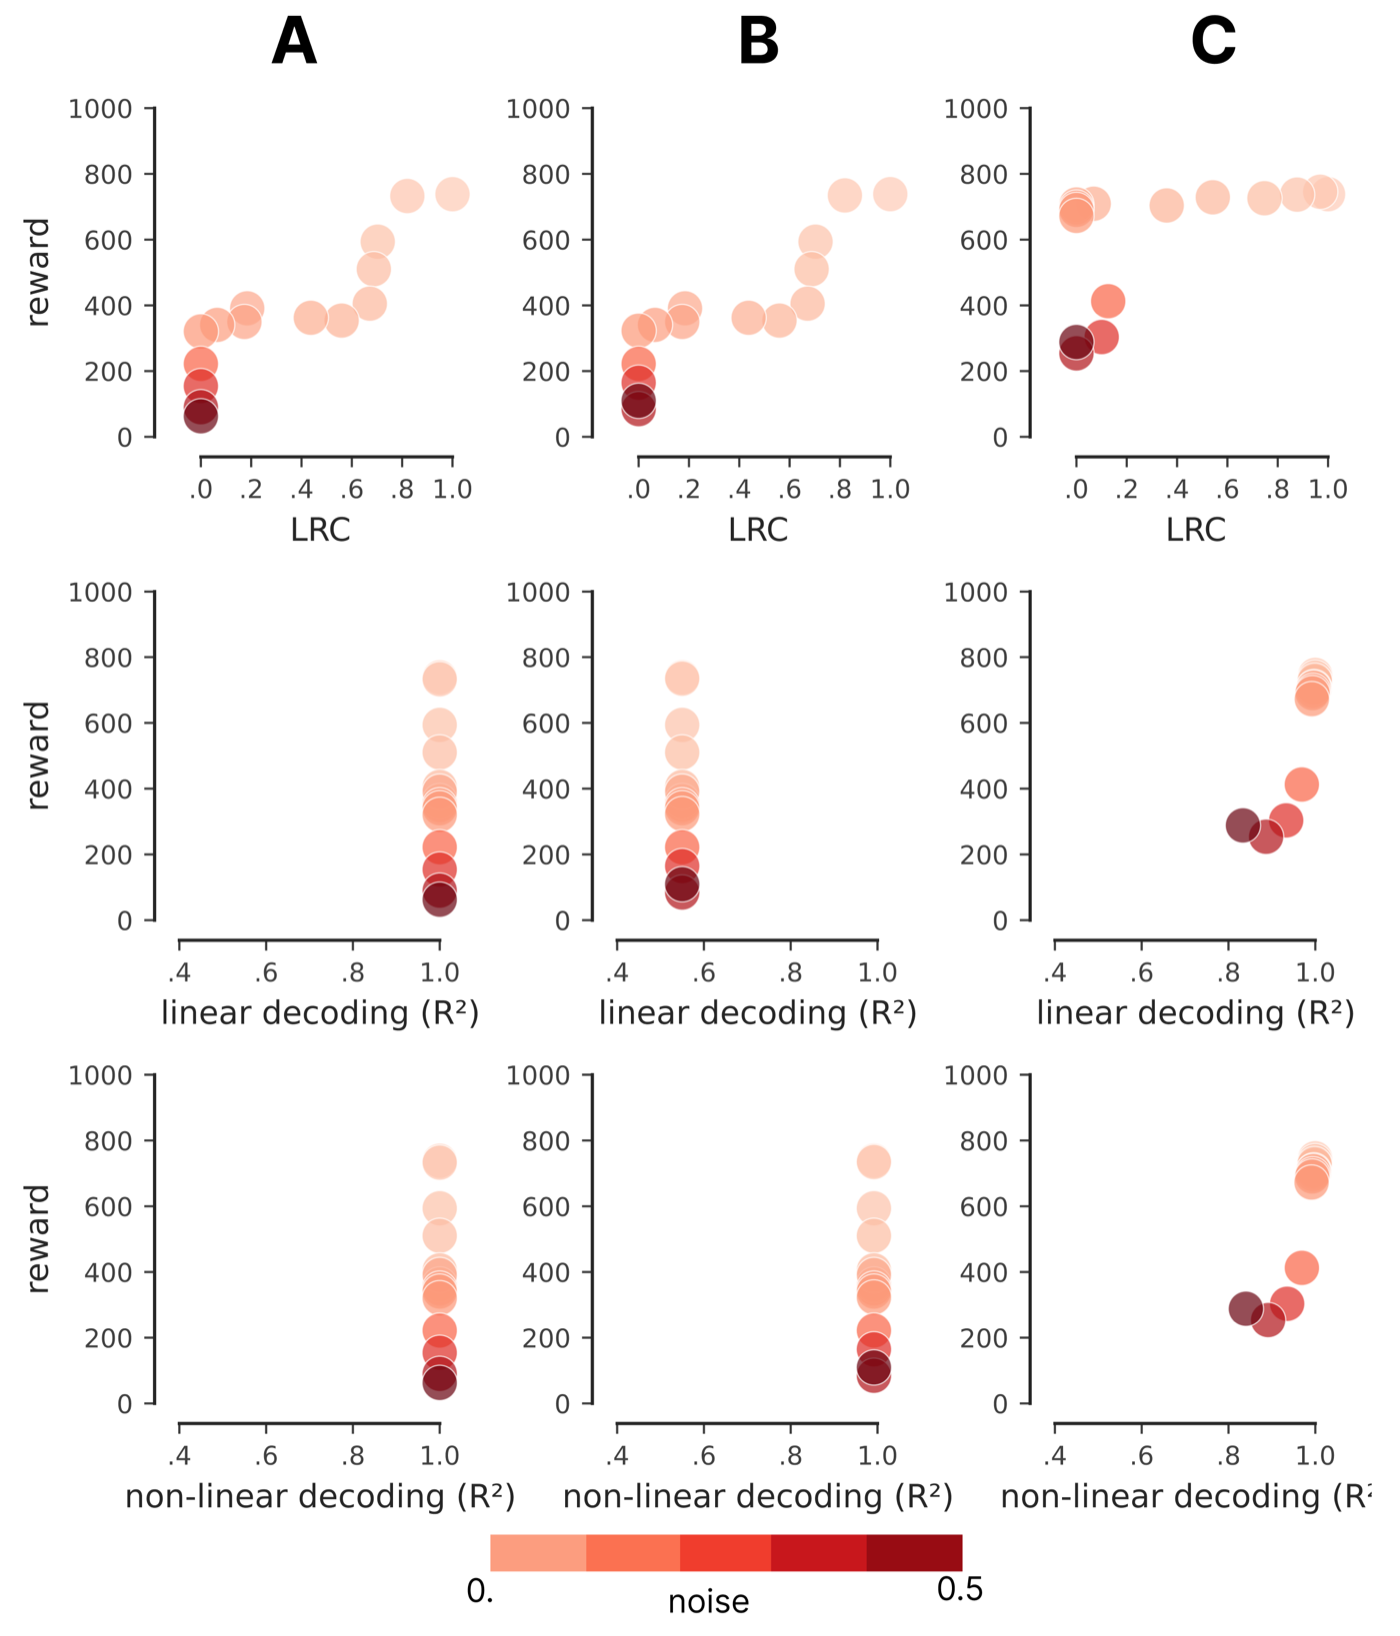
All three columns use CartPole swing-up with an oracle planner, that is, model-predictive control with the true simulator, so no world model is learned. In column A the encoder is the identity and noise is added to the oracle transitions. Linear and nonlinear decoding stay at , so probes cannot see the failure, while reward falls with LRC. Column B applies the same dynamics noise after an invertible nonlinear mix. Linear decoding is poor even without noise, because the coordinates are nonlinear, whereas nonlinear decoding stays at 1 and reward again tracks LRC.
Column C keeps the transitions exact and corrupts the inverse encoder. Decoding remains high and reward can stay high even as LRC collapses: encoder errors are amplified over the rollout before reward or probes break. Both the representation and the dynamics model can limit task performance, which motivates evaluating latent prediction, state decoding and reward together.
High reward does not imply faithful latent dynamics
- 01Reward does not reveal whether the dynamics were learned. Task reward alone does not show whether a world model learns accurate latent dynamics or preserves the underlying physical state. LRC and state decoding expose these failures directly.
- 02Pixel models struggle to recover velocity. Providing velocity explicitly improves latent prediction, but does not fully close the gap to state-based models.
- 03Nonlinear observations make dynamics hard to learn. Even when the underlying state is fully observed, nonlinear transformations make both the representation and its dynamics substantially harder to learn.
Three world-model families on three control tasks
DreamerV3 is reconstruction-based and reward-driven, TD-MPC2 is reconstruction-free but reward-driven, and LeWM is reconstruction-free and reward-free: it learns through self-supervised latent prediction and plans with model-predictive control as a post-hoc step.
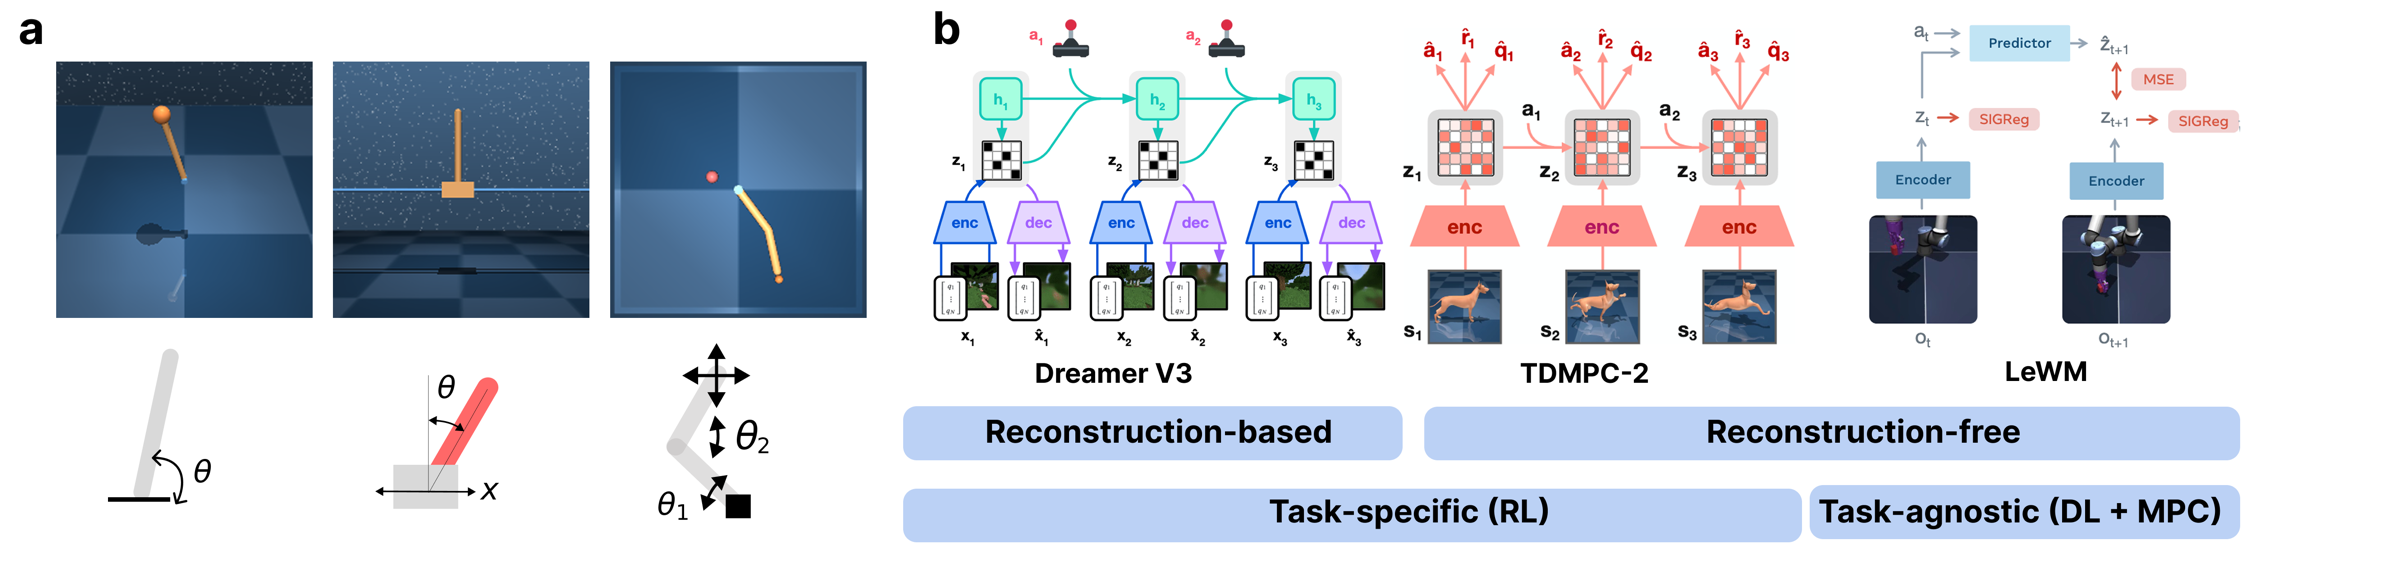
Pendulum and CartPole have nontrivial unforced dynamics, whereas Reacher stays at rest without control. Every model is trained on raw state vectors and on rendered pixels, with four seeds per model, modality and environment. LRC is computed on 1,000 evaluation episodes of 100 steps from a random policy with broad state-space coverage, and reward is summed over episodes of 500 steps.
These environments are deliberately simple. Doing well on them does not imply that a model will scale to harder settings, but if it cannot learn accurate dynamics here, it is difficult to expect it to do so in more complex systems.
Task performance does not imply accurate latent prediction
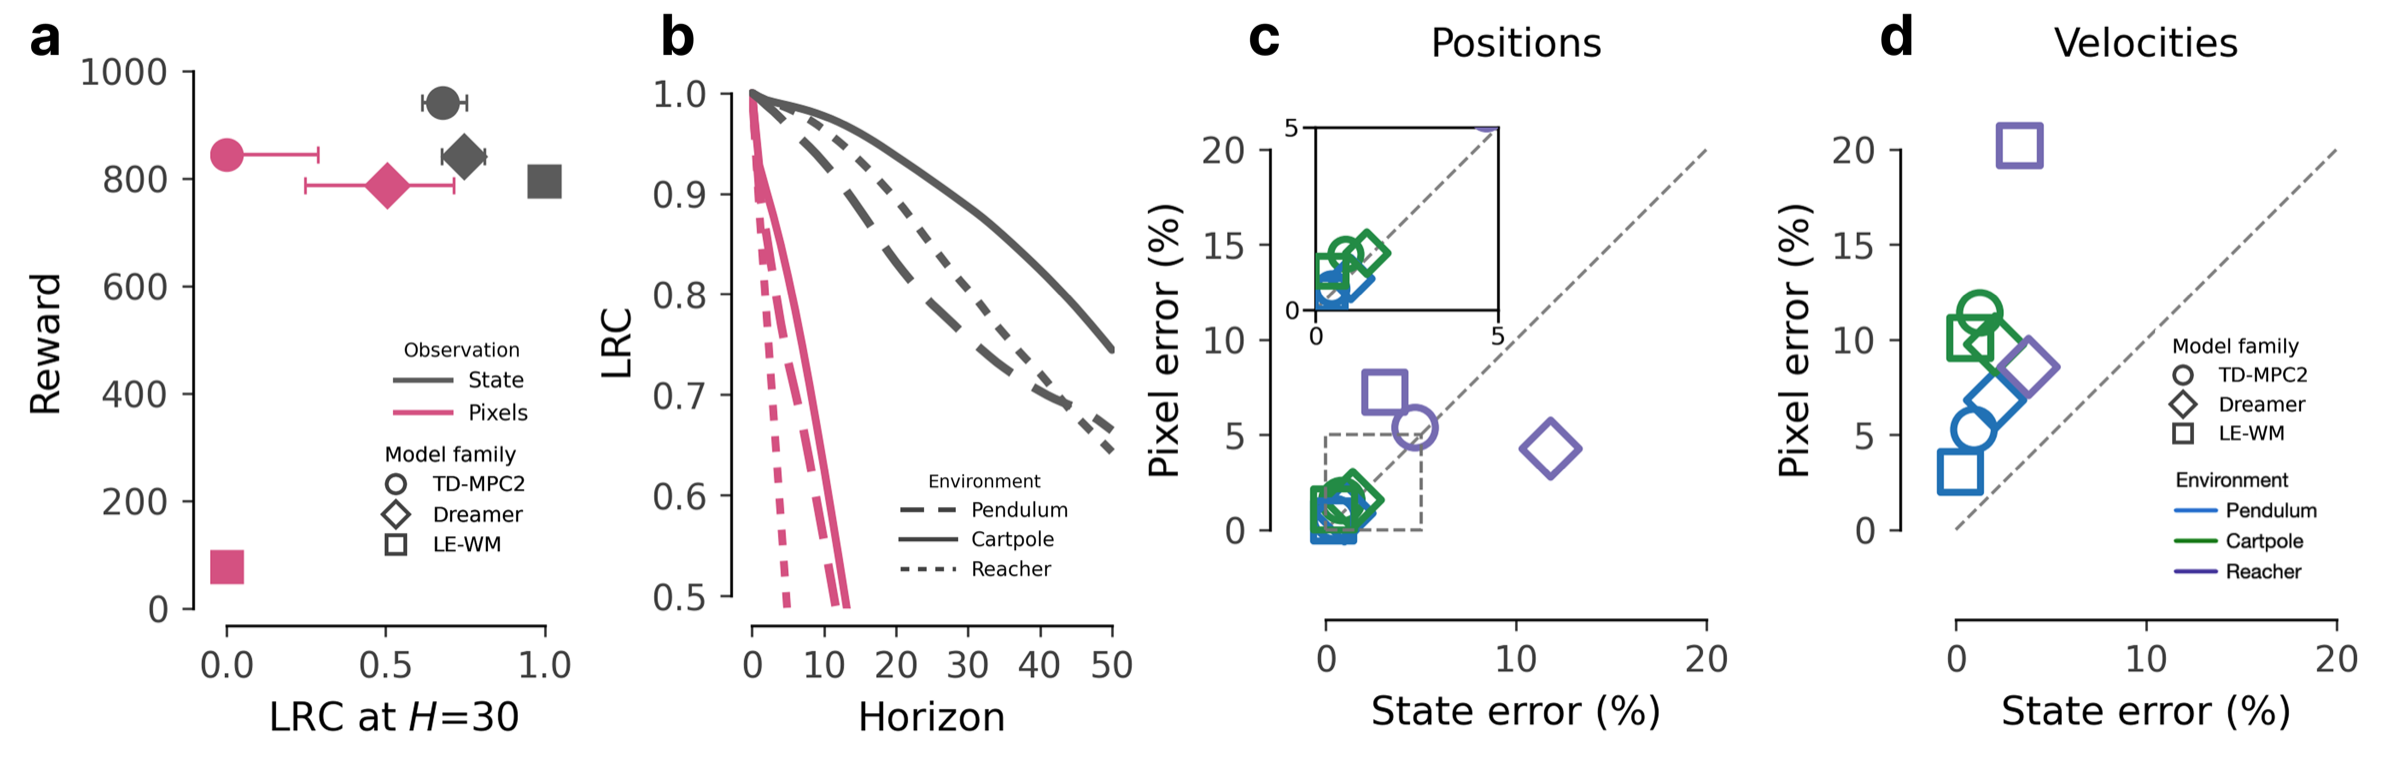
Reward and LRC capture distinct aspects of a world model. Models can reach high reward while their latent rollouts are inaccurate only a few steps into the future. The dissociation is clearest for the task-trained TD-MPC2 and DreamerV3, whose controllers solve the task despite very low LRC from pixels. Their objectives may permit task-specific shortcuts, or their policy and value networks may compensate for inaccurate latent dynamics.
LeWM is pretrained and then plans with model-predictive control, so it cannot take this shortcut by design. It needs sufficiently high LRC to obtain reward, and from pixels its rollouts do not reach that bar on the tested environments.
Pixel observations degrade latent prediction
State inputs provide the physical variables directly, whereas pixel inputs require the model to infer them from a high-dimensional nonlinear observation and from temporal context. Prediction degrades in both modalities, but pixel-based rollouts deteriorate faster and approach the persistence baseline (Fig. 4b).
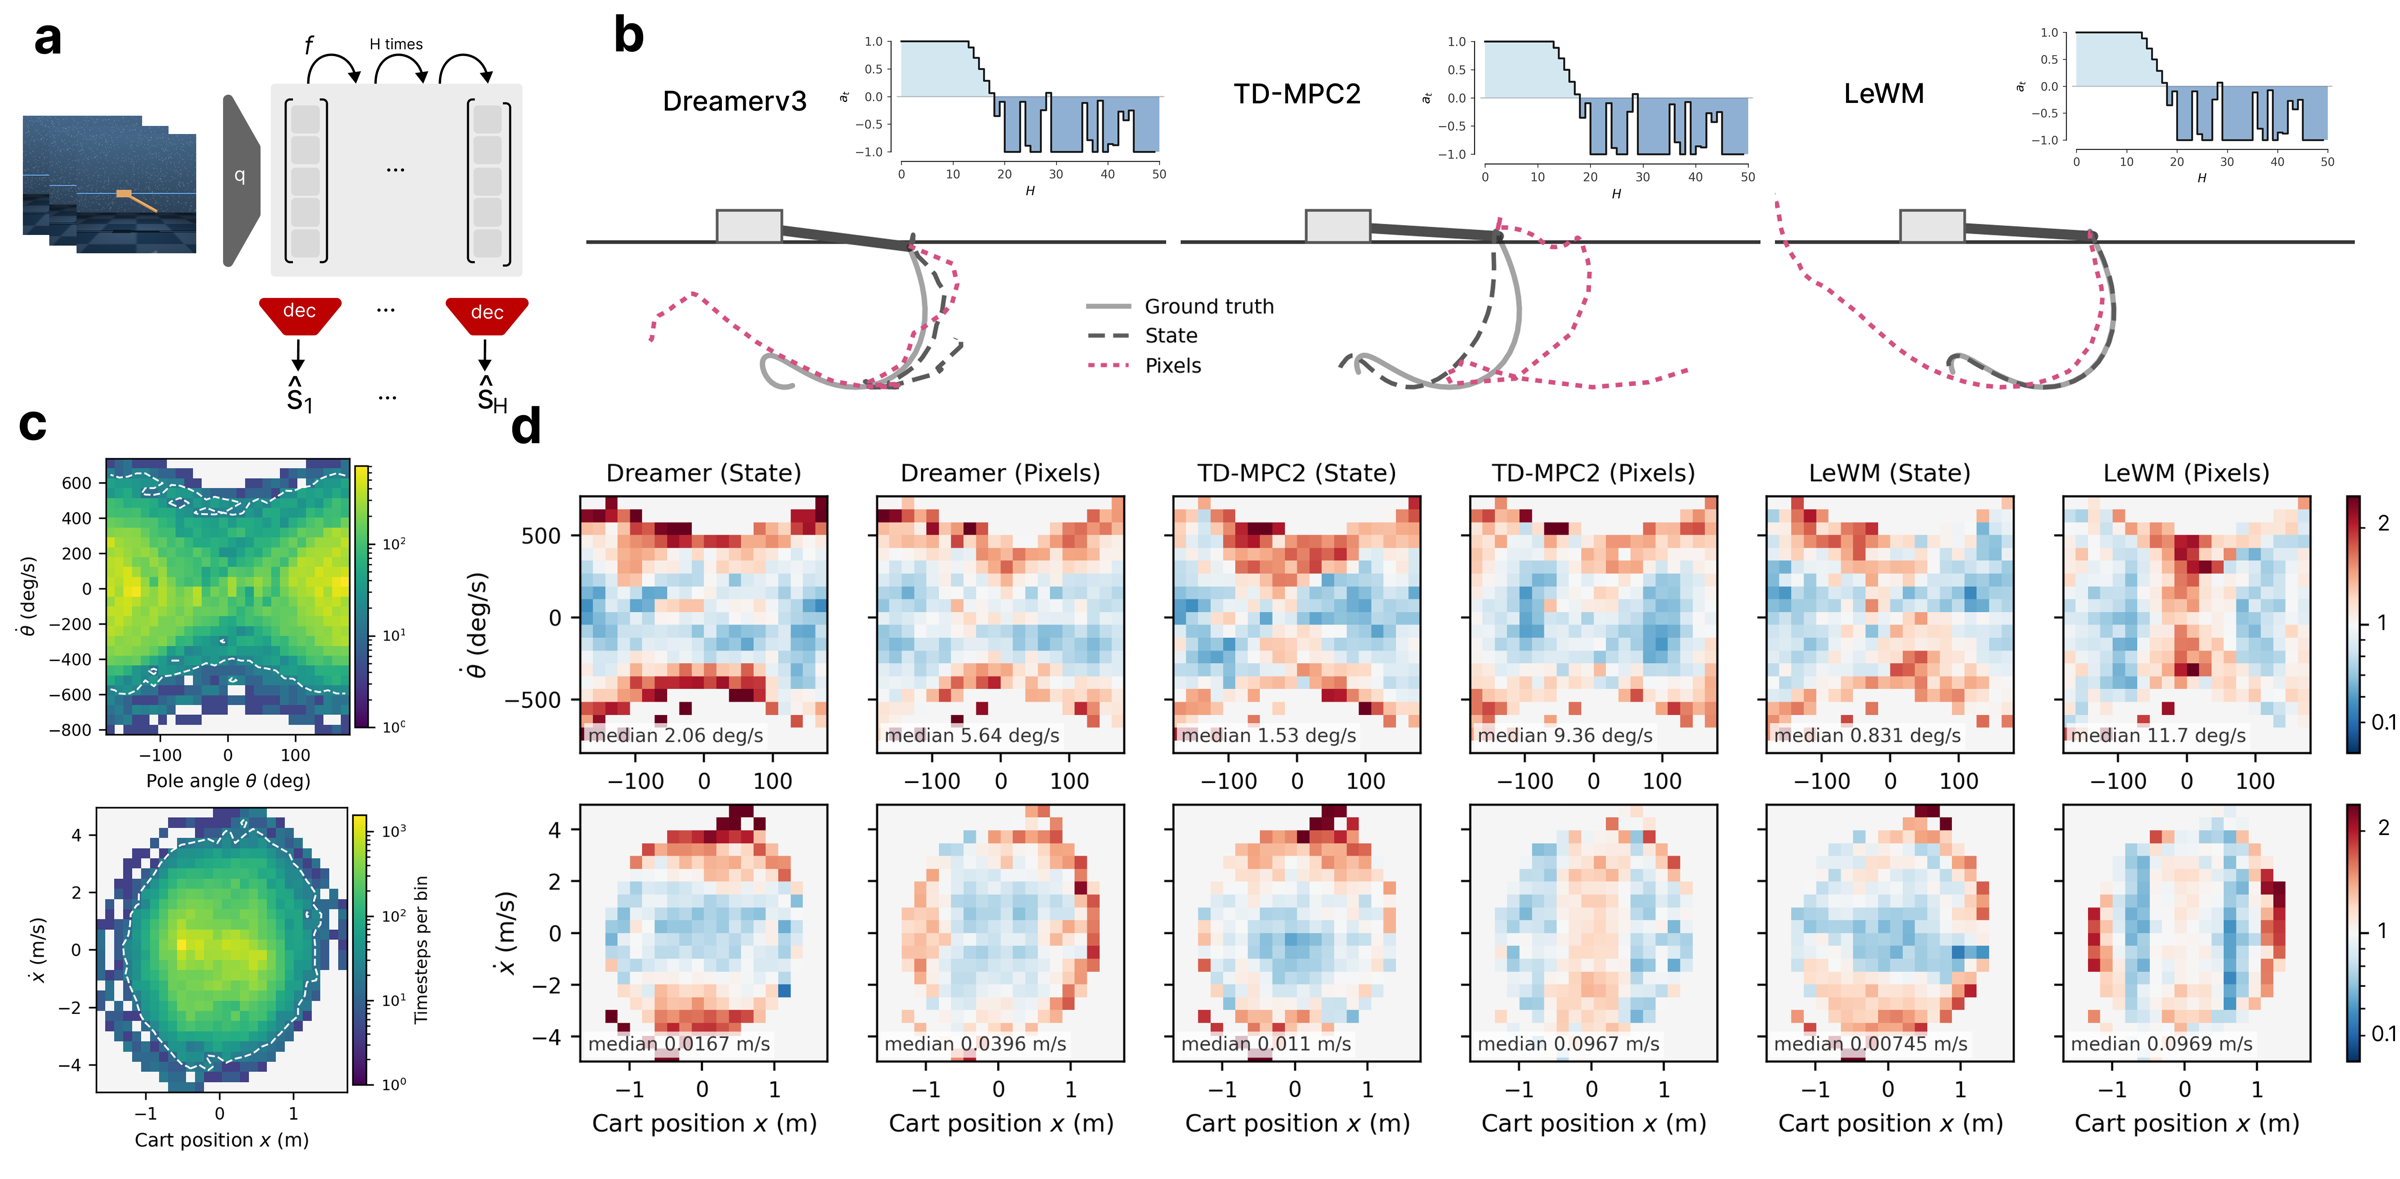
Across all three model families, predictions from pixels depart from the realized trajectory within 30 control steps, only 0.6 s of simulated time.
Accurate latent prediction needs an encoder that retains the predictive state and dynamics that evolve it correctly. Decoding the state from frozen latents separates the two. Positions are decoded with low error (0–7%) in most conditions, with small differences between state and pixel inputs. Velocities are decoded less accurately (3–22%), and state models outperform pixel models by a large margin (Fig. 4c–d).
On CartPole, velocity errors grow with large velocities, where the system evolves fastest and errors compound over the rollout. The pattern appears for both input modalities, but the median error is roughly 2–15× larger for pixel-based models.
Missing velocities explain part of the pixel–state gap
The physical state is Markovian, whereas a single pixel frame is not, so velocities have to be inferred from temporal context. We test this on CartPole by giving pixel models the ground-truth cart and pole velocities, during evaluation only at initialization. As a negative control, we reduce the temporal context from three frames to one.
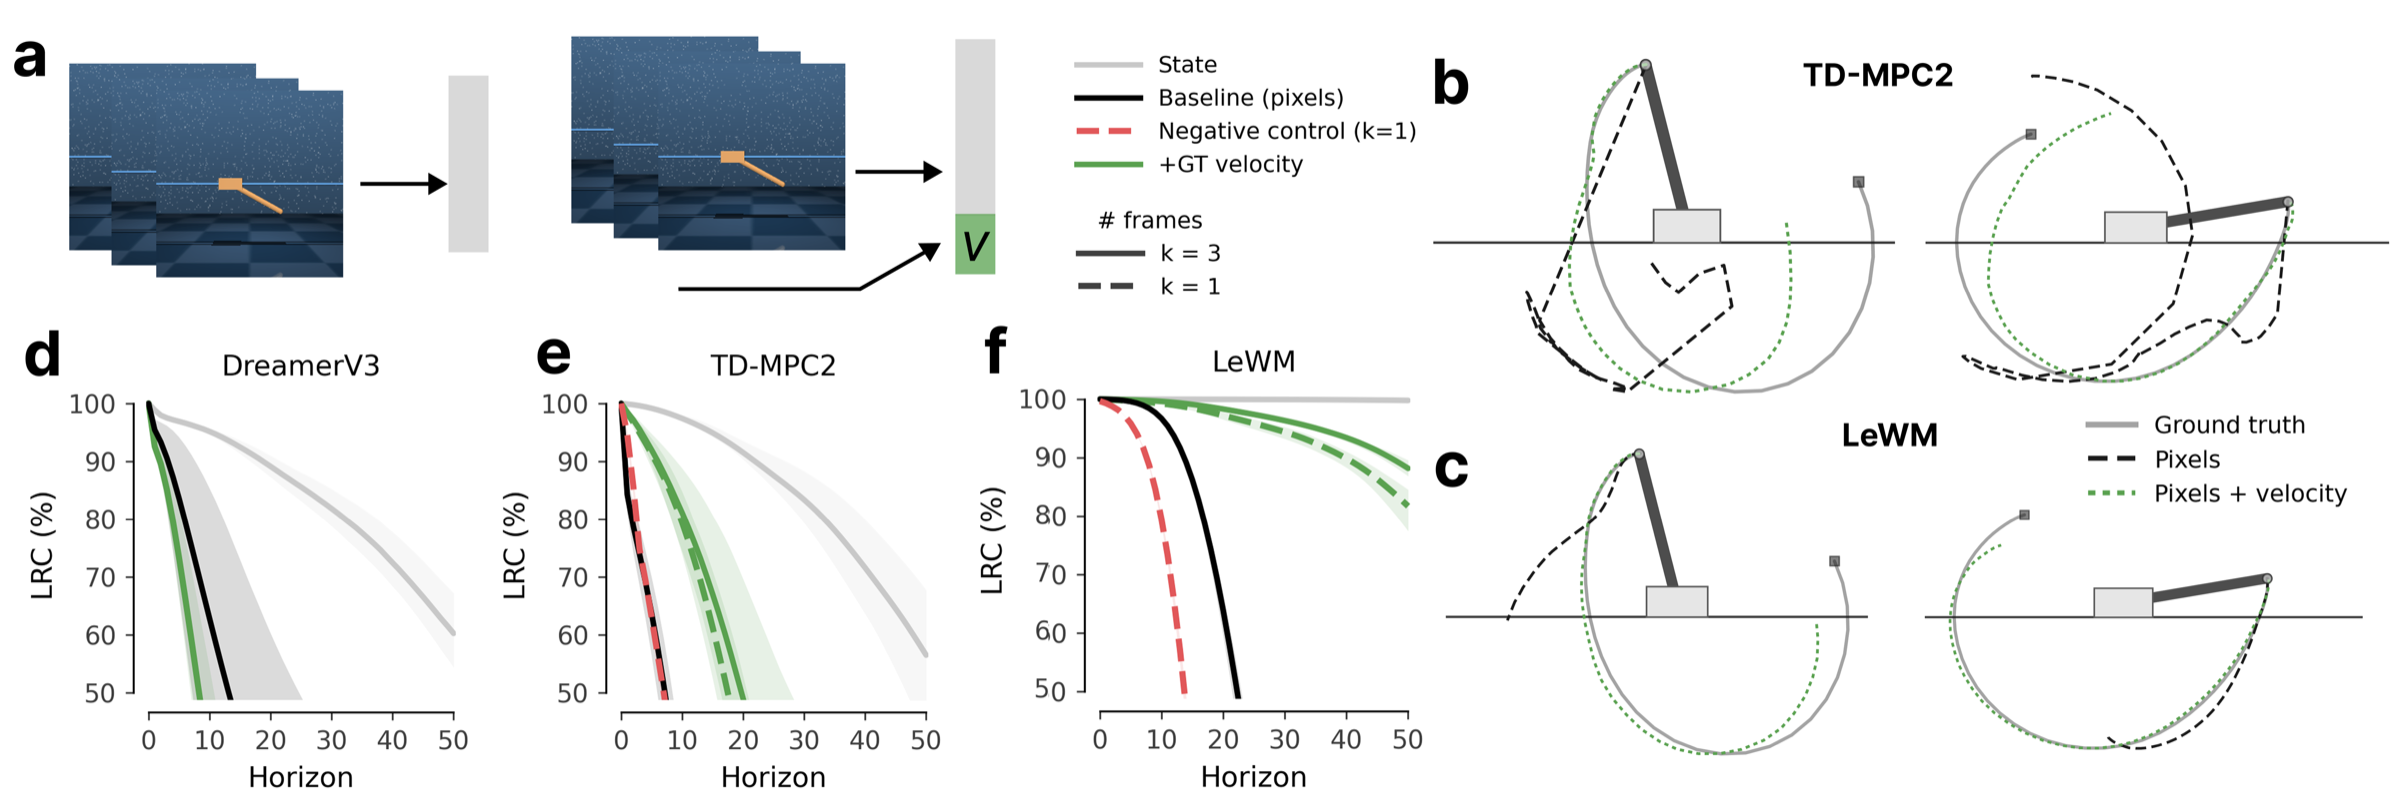
Adding velocity substantially improves latent prediction for TD-MPC2 and LeWM, with both reduced and full temporal context. For LeWM with three frames, LRC at rises from 1.2% to 96.3%. It has no such effect on DreamerV3, possibly because the velocity reaches its RSSM posterior but not its prior.
The intervention changes the representation as intended. With a single frame, the normalized velocity-decoding error is about 130% for TD-MPC2 and LeWM, and providing velocity reduces it to about 1–2%.
Better velocity representations do not consistently increase reward. With three frames, TD-MPC2 changes little, LeWM stays far below its state-input reward (178 versus 757), and DreamerV3 performs worse. CartPole swing-up needs coordinated actions over more than 30 steps, so better LRC at is not enough to plan the full motion. Velocity explains part of the gap between pixel and state inputs, but not all of it.
Learning latent dynamics from nonlinear observations
Pixels are also a nonlinear transformation of the physical state. On CartPole, we replace rendering with an invertible nonlinear map of the state through zero to three mixing layers. The input then contains all state information, but in a coordinate system that is harder to invert.
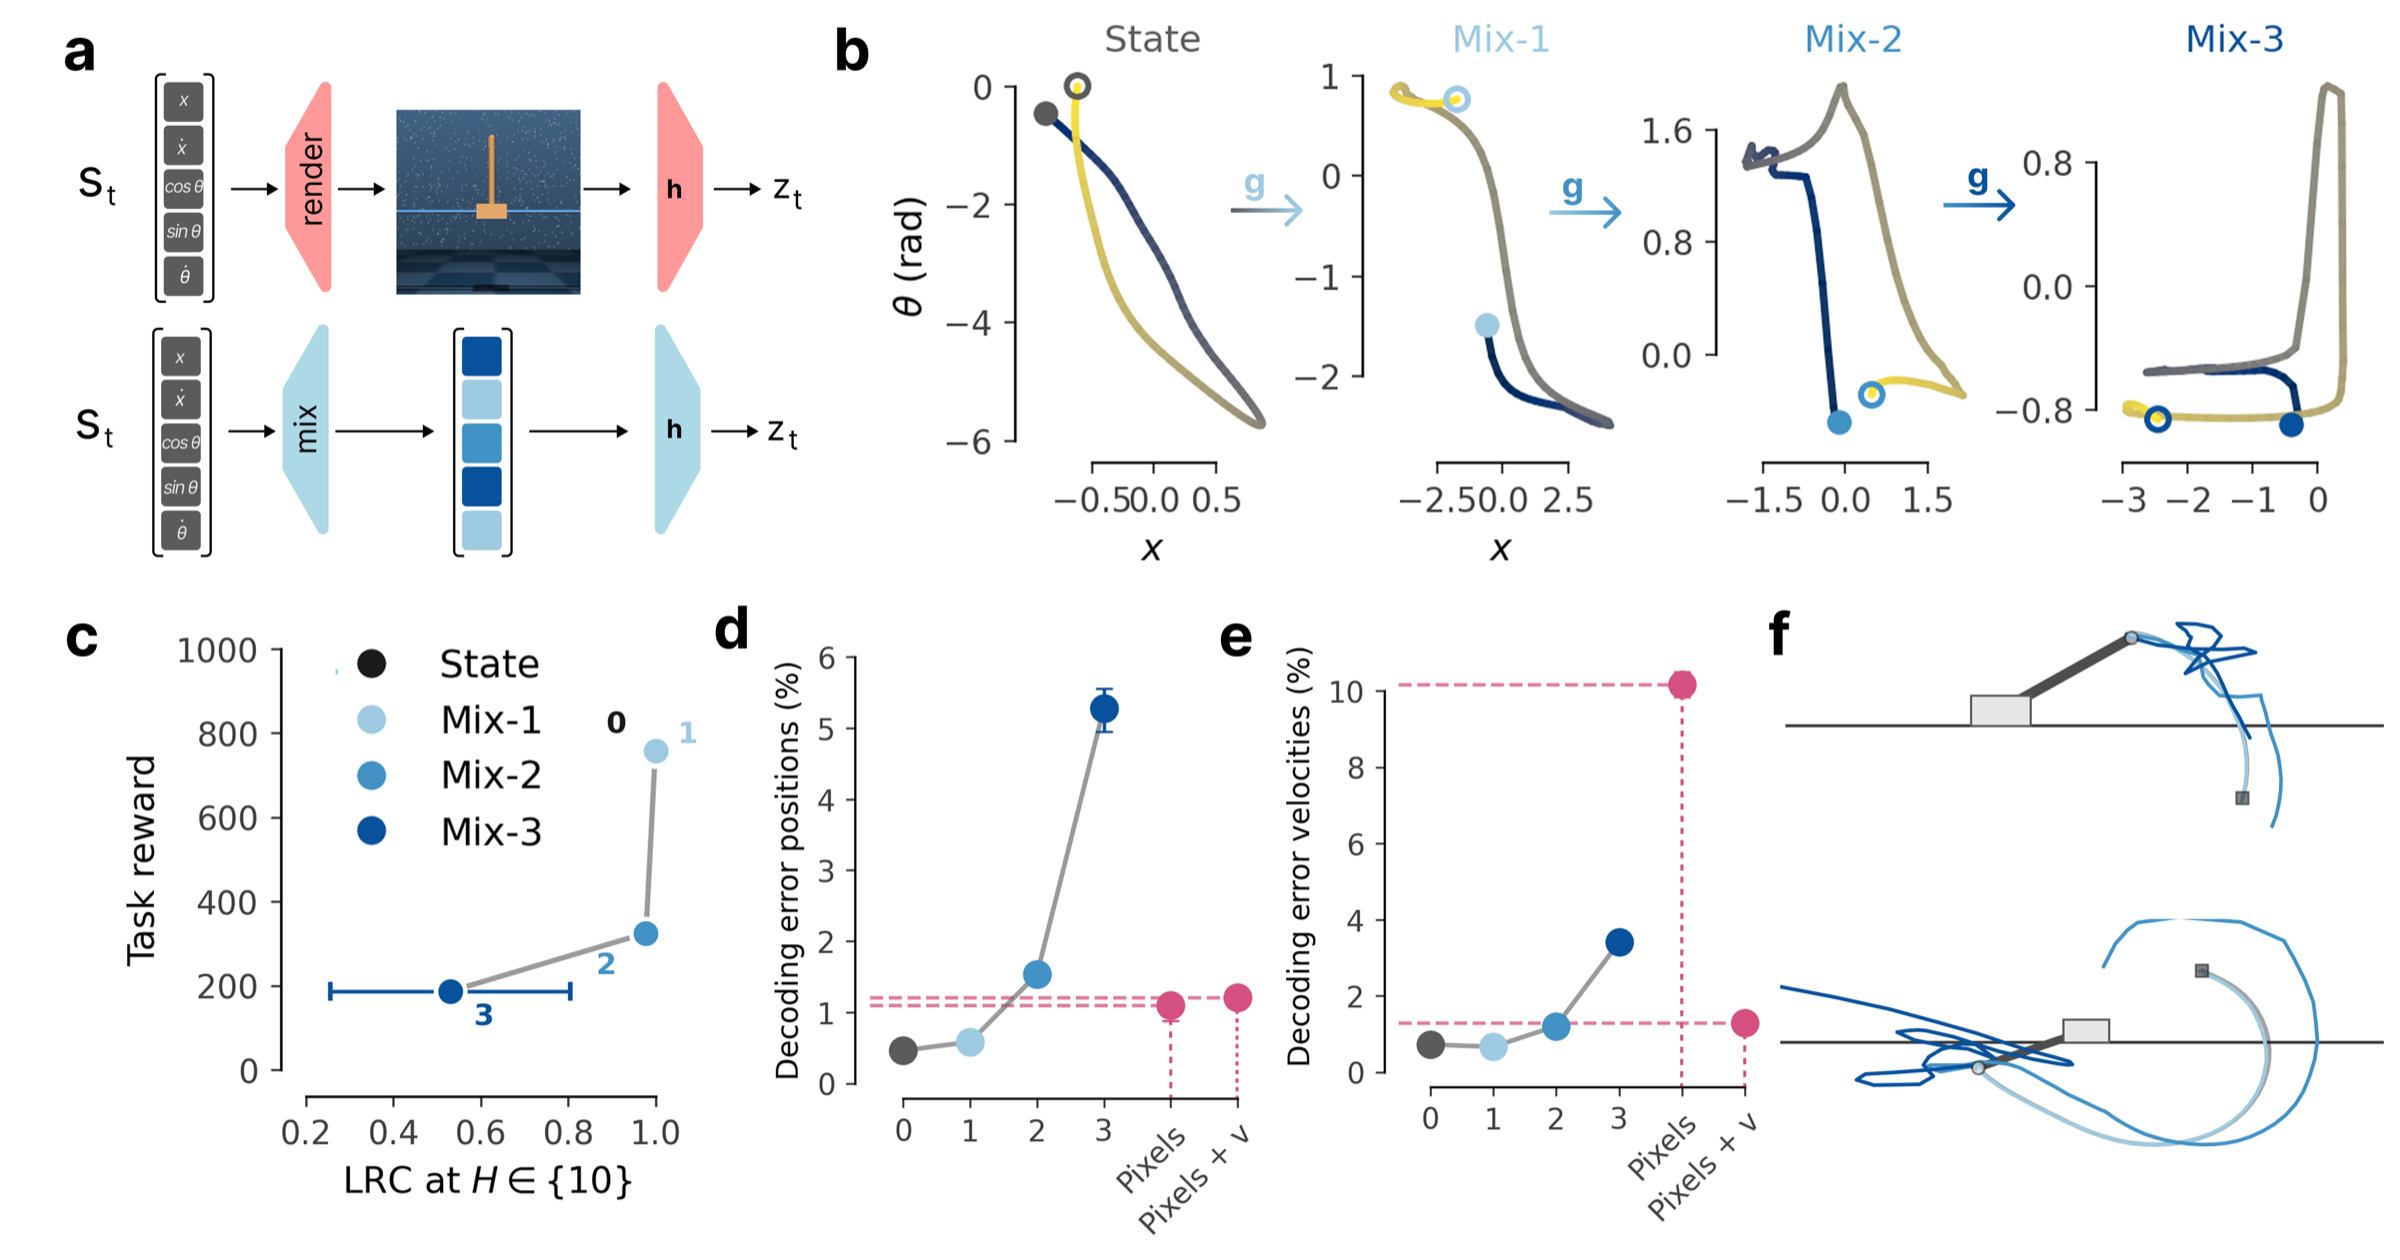
We show LeWM, whose self-supervised objective most directly approximates the faithfulness condition. Task reward and LRC decline together as the number of mixing layers grows, and the controller solves only the conditions with zero and one layer.
With one mixing layer, the normalized position-decoding error is about 0.5% and the task is solved; with two layers it exceeds 1.5% and the task fails. The pixel model, with an error slightly above 1%, does not solve the task either.
Because the mixing is invertible, these failures cannot be attributed to missing information in the input. The evaluated objectives struggle to learn representations from which the physical state is recoverable.
Read the paper
TIMELY: from control tasks to biological dynamics
With TIMELY, we aim to extend the evaluation of latent dynamics to biological time series. We are developing shared datasets, metadata and evaluation protocols across modalities, from controlled dynamical systems to recordings of behavior, neural activity and organoids.
The benchmark is in development and starts with forecasting tasks on controlled systems. Our goal is to make these data accessible, so that the latent descriptions learned by different models can be compared.
TIMELY at Helmholtz Imaging